
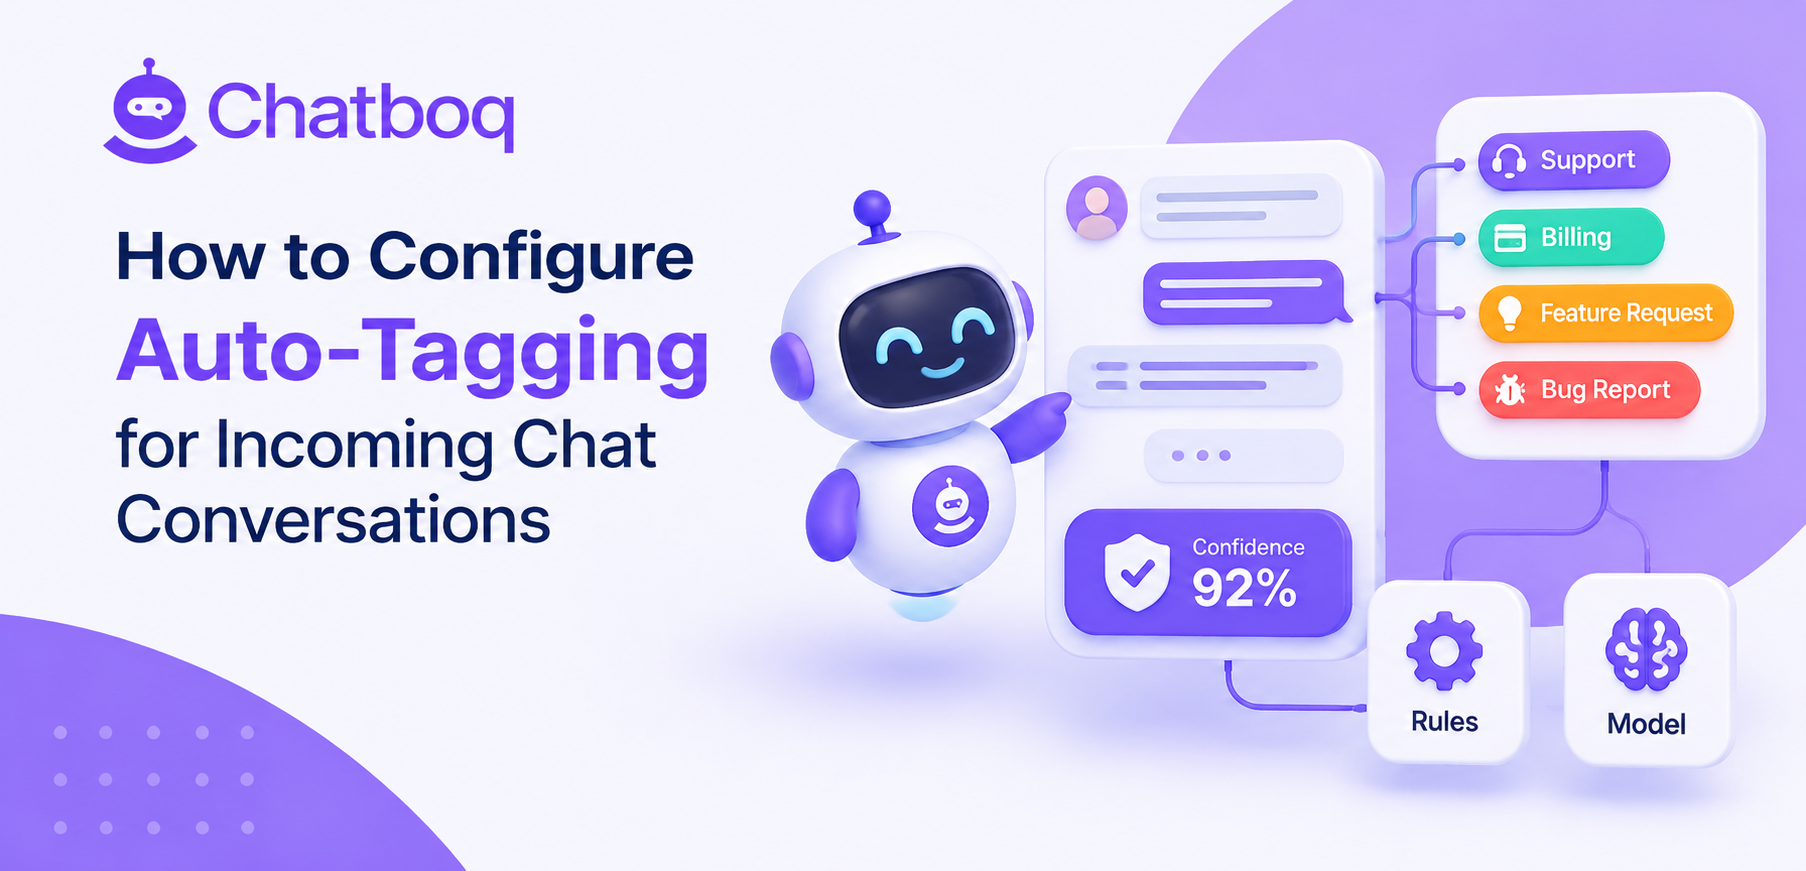
Keyword rules and model classification suit different tags, and using one method for everything produces poor accuracy somewhere.
Where rules work well
Tags identified by specific terms, product names, reference formats or exact phrases are handled reliably by rules and are easier to explain and audit.
Rules are also immediate, requiring no training data, which makes them the right choice for a tag introduced alongside a new product.
Where models work better
Tags representing a concept rather than a vocabulary, such as frustration or confusion about a process, cannot be captured by keyword lists.
These need classification trained on examples, and attempting to express them as rules produces a growing list that never quite works.
Metadata rather than content
Some tags derive from context rather than conversation content, such as the page, the customer tier or whether the conversation escalated.
Applying these from metadata is entirely reliable and should not be left to content classification, which will occasionally get them wrong.
Combining methods
A hybrid where rules handle unambiguous cases and a model handles the rest usually outperforms either alone, particularly for high-volume tags.
The rules also serve as a check, since a model disagreeing with a clear rule match is a signal worth reviewing.
Starting from existing data
Where conversations have been tagged manually for a period, that history is training data and makes model-based classification viable immediately.
Checking its consistency first matters, since training on inconsistent manual tagging reproduces the inconsistency at scale.
 ChatGPT
 Perplexity
 Claude

Leave a Comment
Your email address will not be published. Required fields are marked *
By submitting, you agree to receive helpful messages from Chatboq about your request. We do not sell data.