
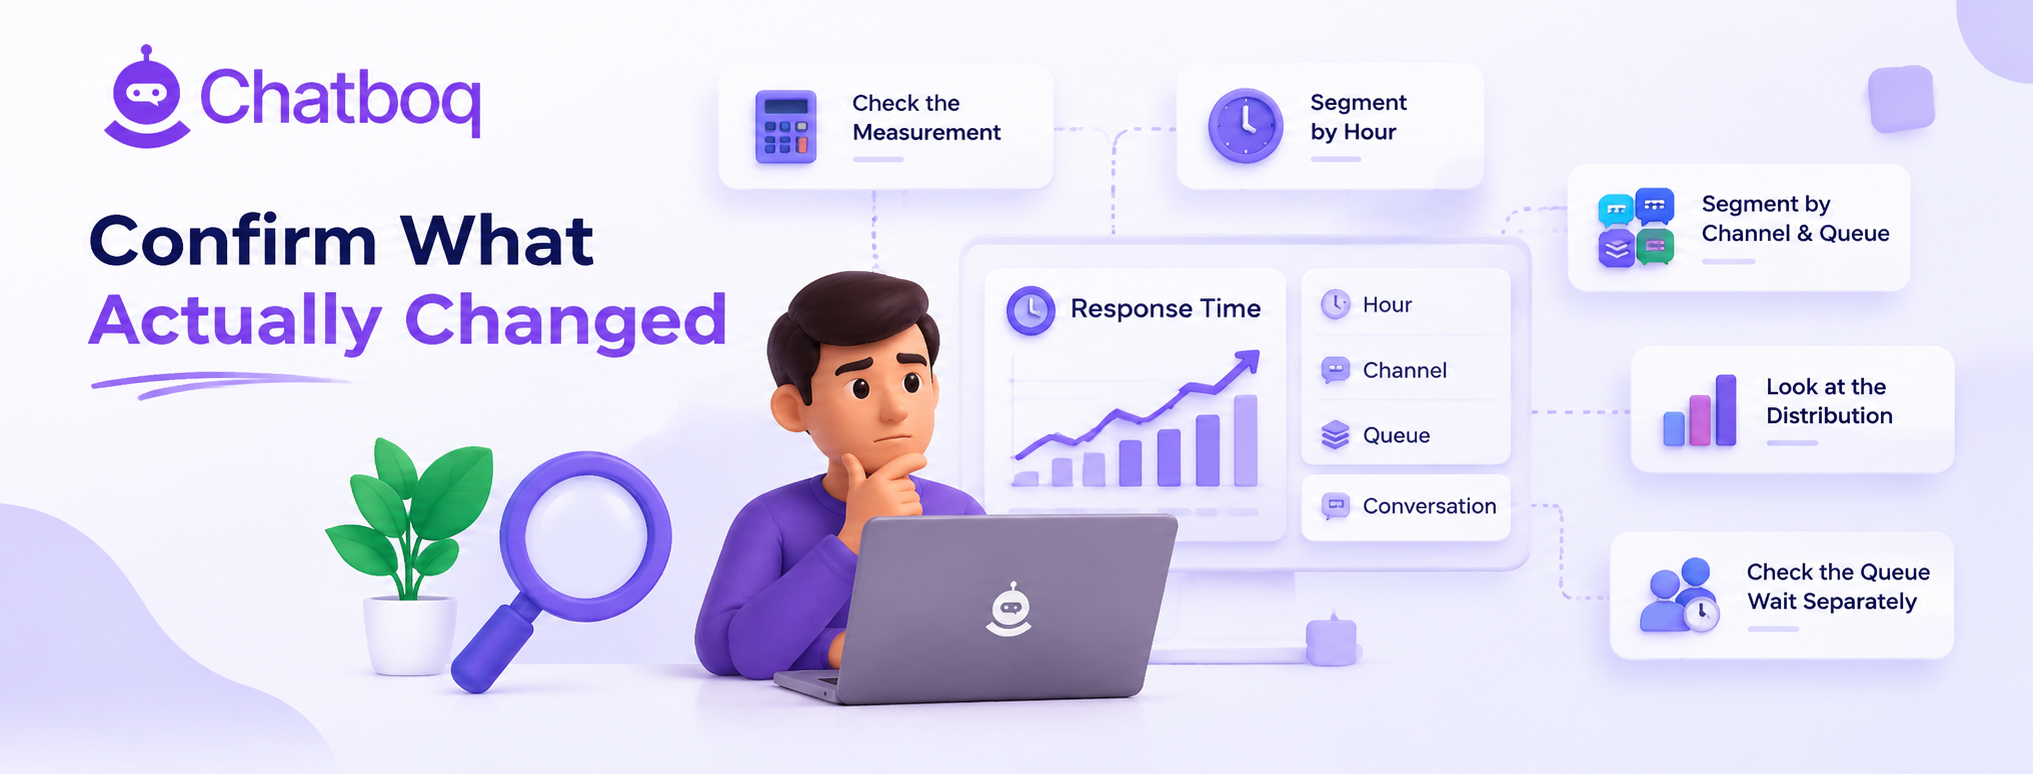
Check the definition and the segmentation before investigating causes, since both explain a substantial proportion of apparent increases.
Check the measurement
A change in what counts as a first response, such as excluding automated acknowledgements that were previously counted, produces an immediate apparent increase.
This is worth ruling out first because it costs minutes and explains a surprising number of cases.
Segment by hour
An average rising because of a few badly covered hours is a scheduling problem rather than a capacity one, and the fix is very different.
Plotting response time by hour of day almost always localises the problem to a specific window.
Segment by channel and queue
A blended figure across channels with different expectations hides which one deteriorated, and one queue can move the average alone.
This segmentation frequently identifies the cause without any further investigation.
Look at the distribution
A rising mean with a stable median means a small number of very slow responses, which is a different problem from everything being slower.
Reporting a high percentile alongside the average distinguishes these immediately.
Checking the queue wait separately
Time spent in the queue and time an agent takes to reply after assignment are different problems, and separating them points at capacity or behaviour respectively.
Most reporting combines the two, which is why the cause is frequently misidentified.
 ChatGPT
 Perplexity
 Claude

Leave a Comment
Your email address will not be published. Required fields are marked *
By submitting, you agree to receive helpful messages from Chatboq about your request. We do not sell data.